Operating-Systems
Question 1 |
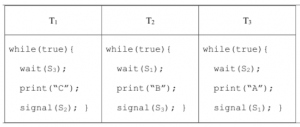 Which initialization of the semaphores would print the sequence BCABCABCA….?
S 1 = 1; S 2 = 1; S 3 = 1 | |
S 1 = 1; S 2 = 1; S 3 = 0 | |
S 1 = 1; S 2 = 0; S 3 = 0 | |
S 1 = 0; S 2 = 1; S 3 = 1 |
Question 2 |
Circular wait is a necessary condition for the formation of deadlock. | |
In a system where each resource has more than one instance, a cycle in its wait-for graph indicates the presence of a deadlock. | |
If the current allocation of resources to processes leads the system to unsafe state, then deadlock will necessarily occur. | |
In the resource-allocation graph of a system, if every edge is an assignment edge, then the system is not in deadlock state. |
Question 3 |
P = 4, Q = 10, R = 6, S = 2 | |
P = 2, Q = 9, R = 5, S = 1 | |
P = 4, Q = 12, R = 5, S = 4 | |
P = 3, Q = 7, R = 7, S = 3 |

The combinations of given context switches are possible for options A,B and C. However, we can observe that option D does not follow the context switch. Hence, D is the answer.
Question 4 |
102 |
For linked allocation we have to trace the first 51 blocks, which requires 51 disk accesses. Similarly for contiguous allocation we have to move the block number 50-100 after insertion of a new block, which takes 51 accesses. Hence, the answer is 51+51 = 102.
Question 5 |
7, 2, 7, 3, 2, 5,3, 4, 6, 7, 7,1, 5, 6,1
the page fault rate, defined as the ratio of number of page faults to the number of memory accesses (rounded off to one decimal place) is_________.
0.60 |
Question 6 |
A memory page containing a heavily used variable that was initialized very early and is in constant use is removed when
LRU page replacement algorithm is used | |
FIFO page replacement algorithm is used | |
LFU page replacement algorithm is used | |
None of the above |
In LRU which can eliminate (or) removed which is least recently used.
In LFU the frequency of the page is more. So it is in constant use so cannot be replaced.
Question 7 |
Consider the following heap (figure) in which blank regions are not in use and hatched region are in use.

The sequence of requests for blocks of size 300, 25, 125, 50 can be satisfied if we use
either first fit or best fit policy (any one) | |
first fit but not best fit policy | |
best fit but first fit policy | |
None of the above |
So, request for 300 will be satisfied by 350 size block reducing the free size to 50.
Request for 25, satisfied by 125 size block, reducing it to 125.
Request for 125 satisfied by the 125 size block.
And request for 50 satisfied by 50 size block.
So, all requests can be satisfied.
In best fit strategy, a block request is satisfied by the smallest block in which can fit it. So, request for 300 will be satisfied by 350 size block reducing the free size to 50.
Request for 25, satisfied by 50 size block as its the smallest size that fits 25, reducing it to 25.
Request for 125, satisfied by 150 size block, reducing it to 25.
Now, request for 50 cannot be satisfied as the two 25 size blocks are not contiguous.
Question 8 |
Consider the resource allocation graph given in the figure.

(a) Find if the system is in a deadlock state. (b) Otherwise, find a safe sequence.
Theory Explanation. |
Question 9 |
Consider allocation of memory to a new process. Assume that none of the existing holes in the memory will exactly fit the process’s memory requirement. Hence, a new hole of smaller size will be created if allocation is made in any of the existing holes. Which one of the following statements is TRUE?
The hole created by worst fit is always larger than the hole created by first fit. | |
The hole created by best fit is never larger than the hole created by first fit.
| |
The hole created by first fit is always larger than the hole created by next fit. | |
The hole created by next fit is never larger than the hole created by best fit. |
Question 10 |
Consider the following statements about process state transitions for a system using preemptive scheduling.
- I. A running process can move to ready state.
II. A ready process can move to running state.
III. A blocked process can move to running state.
IV. A blocked process can move to ready state.
Which of the above statements are TRUE?
II and III only | |
I, II and III only
| |
I, II, III and IV
| |
I, II and IV only
|

Question 11 |
Consider the following set of processes, assumed to have arrived at time 0. Consider the CPU scheduling algorithms Shortest Job First (SJF) and Round Robin (RR). For RR, assume that the processes are scheduled in the order P1,P2,P3,P4.
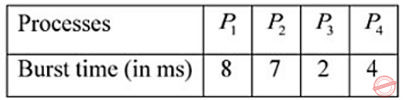
If the time quantum for RR is 4 ms, then the absolute value of the difference between the average turnaround times (in ms) of SJF and RR (round off to 2 decimal places) is _____.
5.25 |

Turn Around Time = (21 – 0) + (13 – 0) + (2 – 0) + (6 – 0), Average = 42/4 = 10.50

Turn Around Time (TAT) = (18 – 0) + (21 – 0) + (10 – 0) + (14 – 0), Average = 63/4 = 15.75
Absolute difference = |10.50-15.75| = 5.25
Question 12 |
Each of a set of n processes executes the following code using two semaphores a and b initialized to 1 and 0, respectively. Assume that count is a shared variable initialized to 0 and not used in CODE SECTION P.
wait (a); count = count+1;
if (count==n) signal (b);
signal (a); wait (b); signal (b);
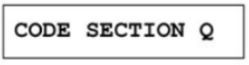
What does the code achieve?
It ensures that all processes execute CODE SECTION P mutually exclusively. | |
It ensures that at most two processes are in CODE SECTION Q at any time. | |
It ensures that no process executes CODE SECTION Q before every process has finished CODE SECTION P.
| |
It ensures that at most n-1 processes are in CODE SECTION P at any time.
|
Question 13 |
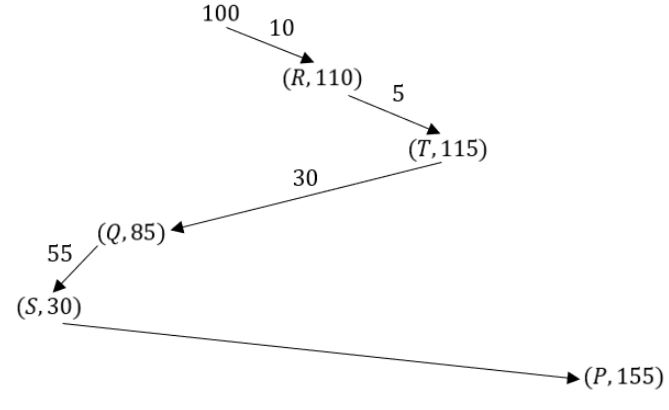
Consider the following five disk access requests of the form (request id, cylinder number) that are present in the disk scheduler queue at a given time.
(P, 155), (Q, 85), (R, 110), (S, 30), (T, 115)
Assume the head is positioned at cylinder 100. The scheduler follows Shortest Seek Time First scheduling to service the requests.
Which one of the following statements is FALSE?
The head reverses its direction of movement between servicing of Q and P. | |
T is serviced before P. | |
R is serviced before P. | |
Q is serviced after S, but before T.
|
Question 14 |
Consider a paging system that uses a 1-level page table residing in main memory and a TLB for address translation. Each main memory access takes 100 ns and TLB lookup takes 20 ns. Each page transfer to/from the disk takes 5000 ns. Assume that the TLB hit ratio is 95%, page fault rate is 10%. Assume that for 20% of the total page faults, a dirty page has to be written back to disk before the required page is read in from disk. TLB update time is negligible. The average memory access time in ns (round off to 1 decimal places) is ______.
154.5 ns |
T=20ns
D=5000ns
h=0.95
p=0.1, 1-p=0.9
d=0.2, 1-d=0.8
EMAT = h×(T+M)+(1-h)[(1-p)×2M+p[(1-d)[D+M]+d(2D+M)]+T]
= 0.95×(20+100)+(1-0.95)[(1-0.1)×200+(0.1)[(1-0.2)[5000+100]+(0.2)(10000+100)]+20]
= 154.5 ns
Question 15 |
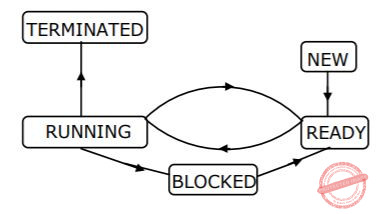
The process state transition diagram in below figure is representative of
a batch operating system | |
an operating system with a preemptive scheduler | |
an operating system with a non-preemptive scheduler | |
a uni-programmed operating system |
So this is preemptive.
Question 16 |
A critical section is a program segment
which should run in a certain specified amount of time | |
which avoids deadlocks | |
where shared resources are accessed | |
which must be enclosed by a pair of semaphore operations, P and V |
Question 17 |
Which of the following is an example of spooled device?
A line printer used to print the output of a number of jobs. | |
A terminal used to enter input data to a running program. | |
A secondary storage device in a virtual memory system. | |
A graphic display device. |
Question 18 |
The correct matching for the following pairs is
         A. Activation record	   1. Linking loader
         B. Location counter	   2. Garbage collection
         C. Reference counts	   3. Subroutine call
         D. Address relocation	   4. Assembler
A – 3 B – 4 C – 1 D – 2 | |
A – 4 B – 3 C – 1 D – 2 | |
A – 4 B – 3 C – 2 D – 1 | |
A – 3 B – 4 C – 2 D – 1 |
An assembler uses location counter value to give address to each instruction which is needed for relative addressing as well as for jump labels.
Reference count is used by garbage collector to clear the memory whose reference count be comes 0.
Linker loader is a loader which can load several compiled codes and link them together into a single executable. Thus it needs to do relocation of the object codes.
Question 19 |
A 1000 Kbyte memory is managed using variable partitions but to compaction. It currently has two partitions of sizes 200 Kbytes and 260 Kbytes respectively. The smallest allocation request in Kbytes that could be denied is for
151 | |
181 | |
231 | |
541 |
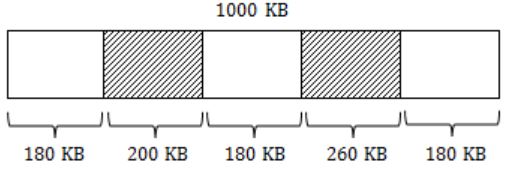
So, smallest allocation request which can be denied is 181 KB.
Question 20 |
A solution to the Dining Philosophers Problem which avoids deadlock is
ensure that all philosophers pick up the left fork before the right fork | |
ensure that all philosophers pick up the right fork before the left fork | |
ensure that one particular philosopher picks up the left fork before the right fork, and that all other philosophers pick up the right fork before the left fork | |
None of the above |
To avoid this, atleast one philosopher should choose its first chopstick in different way so that circular loop is not formed.
Question 21 |
Four jobs to be executed on a single processor system arrive at time 0+ in the order A, B, C, D. their burst CPU time requirements are 4, 1, 8, 1 time units respectively. The completion time of A under round robin scheduling with time slice of one time unit is
10 | |
4 | |
8 | |
9 |
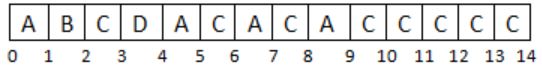
∴ Completion time of A is 9 unit.
Question 22 |
A demand paged virtual memory system uses 16 bit virtual address, page size of 256 bytes, and has 1 Kbyte of main memory. LRU page replacement is implemented using a list whose current status (page number in decimal) is
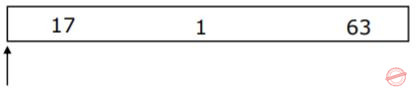
For each hexadecimal address in the address sequence given below
00FF, 010D, 10FF, 11B0
indicate
(i) the new status of the list
(ii) page faults, if any, and
(iii) page replacements, if any
Theory Explanation. |
Question 23 |
The concurrent programming constructs fork and join are as below:
fork
   N = 2
   M = 2
   fork L3
   fork L4
   S1
L1:join N
   S3
L2:join M
   S5
L3:S2
   goto L1
L4:S4
   goto L2
next:
Theory Explanation. |
Question 24 |
A computer system uses the Banker’s Algorithm to deal with deadlocks. Its current state is shown in the table below, where P0, P1, P2 are processes, and R0, R1, R2 are resources types.
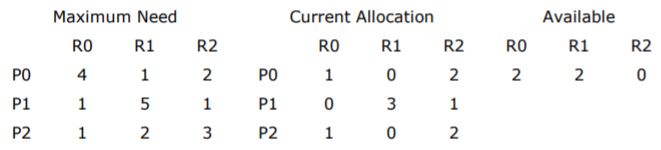
(a) Show that the system can be in this state.
(b) What will the system do on a request by process P0 for one unit of resource type R1?
Theory Explanation. |
Question 25 |
A file system with a one-level directory structure is implemented on a disk with disk block size of 4K bytes. The disk is used as follows:
 Disk-block 0: File Allocation Table, consisting of one 8-bit entry per date block,
               representing the data block address of the next date block in the file
 Disk block 1: Directory, with one 32 bit entry per file:
 Disk block 2: Data block 1;
 Disk block 3: Data block 2; etc.
(a) What is the maximum possible number of files?
(b) What is the maximum possible file size in blocks?
Theory Explanation. |
Question 26 |
Locality of reference implies that the page reference being made by a process
will always be to the page used in the previous page reference | |
is likely to be to one of the pages used in the last few page references | |
will always be to one of the pages existing in memory | |
will always lead to a page fault |
(1) Temporal locality
(2) Spatial locality
(3) Sequential locality
→ In programs related data are stored in consecutive locations and loops in same locations are used repeatedly.
Question 27 |
The correct matching for the following pairs is
(A) Disk Scheduling        (1) Round robin
(B) Batch Processing       (2) SCAN
(C) Time sharing           (3) LIFO
(D) Interrupt processing   (4) FIFO
A – 3 B – 4 C – 2 D – 1 | |
A – 4 B – 3 C – 2 D – 1 | |
A – 2 B – 4 C – 1 D – 3 | |
A – 3 B – 4 C – 3 D – 2 |
Batch processing - FIFO
Time sharing - Round Robin
Interrupt processing - LIFO
Question 28 |
I/O redirection
implies changing the name of a file | |
can be employed to use an existing file as input file for a program | |
implies connection 2 programs through a pipe | |
None of the above
|
Question 29 |
Thrashing
reduces page I/O | |
decreases the degree of multiprogramming | |
implies excessive page I/O | |
improve the system performance |
Question 30 |
Dirty bit for a page in a page table
helps avoid unnecessary writes on a paging device | |
helps maintain LRU information | |
allows only read on a page | |
None of the above |
Question 31 |
An operating system contains 3 user processes each requiring 2 units of resource R. The minimum number of units of r such that no deadlocks will ever arise is
3 | |
5 | |
4 | |
6 |
Question 32 |
Each Process Pi, i = 1.......9 is coded as follows
    repeat
           P(mutex)
           {Critical section}
           V(mutex)
    forever
The code for P10 is identical except it uses V(mutex) in place of P(mutex). What is the largest number of processes that can be inside the critical section at any moment?
1 | |
2 | |
3 | |
None of the above |
repeat
{
V(mutex)
C.S.
V(mutex)
}
forever
Now, let me say P1 is in CS then P1 is in CS
then P10 comes and executes CS (upon mutex).
Now, P2 comes (down on mutex).
Now P10 moves out of CS (again binary semaphore will be 1).
Now P3 comes (down on mutex).
Now P10 comes (upon mutex).
Now P4 comes (down mutex).
⁞
So, if we take P10 'in' and 'out' of CS recursively, all 10 processes can be in CS at same time using binary semaphore only.
Question 33 |
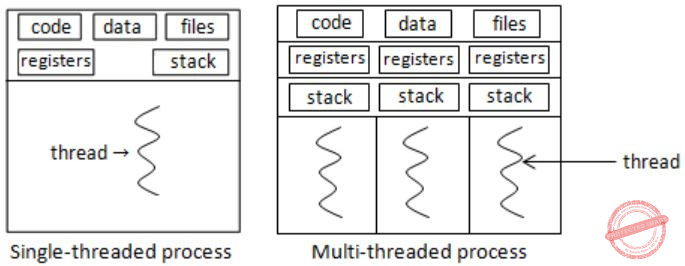
Threads of a process share
global variables but not heap. | |
heap but not global variables. | |
neither global variables nor heap. | |
both heap and global variables. |
Question 34 |
Consider the following CPU processes with arrival times (in milliseconds) and length of CPU bursts (in milliseconds) as given below:

If the pre-emptive shortest remaining time first scheduling algorithm is used to schedule the processes, then the average waiting time across all processes is __________ milliseconds.
3 | |
4 | |
5 | |
6 |

Question 35 |
A multithreaded program P executes with x number of threads and used y number of locks for ensuring mutual exclusion while operating on shared memory locations. All locks in the program are non-reentrant, i.e., if a thread holds a lock l, then it cannot re-acquire lock l without releasing it. If a thread is unable to acquire a lock, it blocks until the lock becomes available. The minimum value of x and the minimum value of y together for which execution of P can result in a deadlock are:
x = 1, y = 2 | |
x = 2, y = 1 | |
x = 2, y = 2 | |
x = 1, y = 1 |
Here a non-reentrant process can’t own the same lock multiple times, so if the process tries to acquire an already owned lock, it will get blocked, and deadlock will happen.
From the above options x=1 (a single thread) and y=1 (a single lock) deadlock is possible when we consider the given situations in question.
Question 36 |
S1: Random page replacement algorithm (where a page chosen at random is replaced) suffers from Belady’s anomaly
S2: LRU page replacement algorithm suffers from Belady’s anomaly
Which of the following is CORRECT?
S1 is true, S2 is true | |
S1 is true, S2 is false | |
S1 is false, S2 is true | |
S1 is false, S2 is false |
Page replacement algorithm suffers from Belady's anomaly when it is not a stack algorithm.
S1: Random page replacement algorithm is not a stack algorithm. So, S1 is true.
S2: LRU is a stack algorithm. Therefore, it doesn't suffer from Belady's anomaly. S2 is false.
Question 37 |
A linker reads four modules whose lengths are 200, 800, 600 and 500 words, respectively. If they are loaded in that order, what are the relocation constants?
0, 200, 500, 600 | |
0, 200, 1000, 1600 | |
200, 500, 600, 800 | |
200, 700, 1300, 2100 |
Now 2nd will start loading at 200, since size is 800, so last address is 999.
Now 3rd module will start loading at 1000, since size is 600. So last address is 1599.
Now 4th module will start loading at 1600 and go till 2099.
Question 38 |
Which of the following is an example of a spooled device?
The terminal used to enter the input data for the C program being executed | |
An output device used to print the output of a number of jobs | |
The secondary memory device in a virtual storage system | |
The swapping area on a disk used by the swapper |
For example in printer if a process attempt to print a document but printer is busy printing another document, the process, instead of waiting for printer to become available, write its output to disk. When the printer becomes available the data on disk is printed.
Spooling allows process to request operation from peripheral device without requiring that the device is ready to service the request.
Question 39 |
When the result of a computation depends on the speed of the processes involved there is said to be
cycle stealing | |
rare condition | |
a time lock | |
a deadlock |
Speed of processes corresponds to ordering of processes.
Question 40 |
A counting semaphore was initialized to 10. Then 6P (wait) operations and 4V (signal) operations were completed on this semaphore. The resulting value of the semaphore is
0 | |
8 | |
10 | |
12 |
S = 10
Now 6P operations and uv operations were completed on this semaphore. So final value of S will be
S = 10 - 6 + 4 = 8
Question 41 |
A computer has six tape drives, with n processes competing for them. Each process may need two drives. What is the maximum value of n for the system to be deadlock free?
6 | |
5 | |
4 | |
3 |
So maximum no. of process for the system to be deadlock free is 5.
Question 42 |
The overlay tree for a program is as shown below:
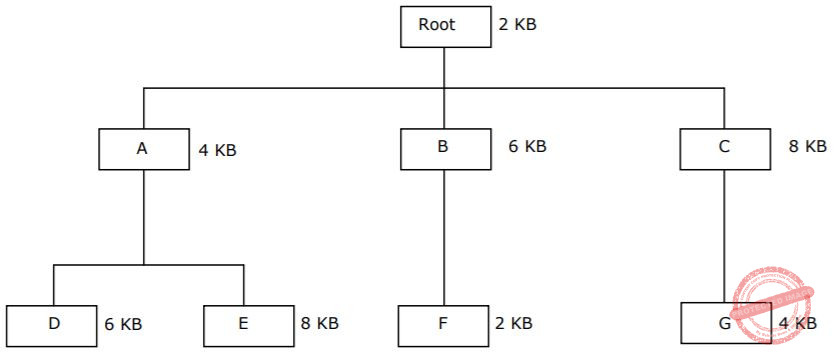
What will be the size of the partition (in physical memory) required to load (and run) this program?
12 KB | |
14 KB | |
10 KB | |
8 KB |
For the above program, maximum memory will be required when running code portion present at leaves.
Maximum requirement
= MAX(12, 14, 10, 14)
= 14
Question 43 |
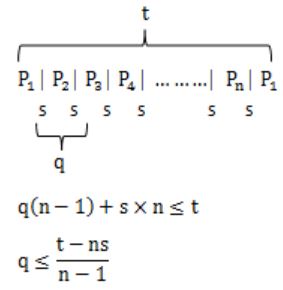
Consider n processes sharing the CPU in a round-robin fashion. Assuming that each process switch takes s seconds, what must be the quantum size q such that the overhead resulting from process switching is minimized but at the same time each process is guaranteed to get its turn at the CPU at least every t seconds?
q ≤ t-ns/n-1 | |
q ≥ t-ns/n-1 | |
q ≤ t-ns/n+1 | |
q ≥ t-ns/n+1 |
Question 44 |
If an instruction takes i microseconds and a page fault takes an additional j microseconds, the effective instruction time if on the average a page fault occurs every k instruction is:
i + (j/k) | |
i + (j*k) | |
(i+j)/ k | |
(i+j)*k |
= service time + page fault rate * page fault service time
= i + 1/k * j
= i + j/k
or
The effective instruction time, if on the average a page fault occurs every k instructions, is:
i + (j / k)
This formula accounts for the normal instruction time (i) and the additional time for a page fault (j), considering the average frequency of page faults (k instructions between page faults).
Question 45 |
(a) Free disk space can be kept track of using a free list or a bit map. Disk addresses require d bits. For a disk with 13 blocks, F of which is free, state the condition under which the free list uses less space than the bit map.
(b) Consider a disk with C cylinders, t tracks per cylinder, s sectors per track and a sector length sl. A logical file dl with fixed record length rl is stored continuously on this disk starting at location (cL,tL,sL), where cL, tL and SL are the cylinder, track and sector numbers, respectively. Derive the formula to calculate the disk address (i.e. cylinder, track and sector) of a logical record n assuming that rl=sl.
Theory Explanation. |
Question 46 |
Listed below are some operating system abstractions (in the left column) and the hardware components or mechanism (in the right column) that they are abstractions of. Which of the following matching of pairs is correct?
    A. Thread                      1. Interrupt
    B. Virtual address space       2. Memory
    C. File system                 3. CPU
D. Signal 4. Disk (A) – 2 (B) – 4 (C) – 3 (D) - 1 | |
(A) – 1 (B) – 2 (C) – 3 (D) – 4 | |
(A) – 3 (B) – 2 (C) – 4 (D) - 1 | |
(A) – 4 (B) – 1 (C) – 2 (D) – 3 |

⇒ Threads are handled by CPU.
⇒ Virtual address is a memory type.
⇒ File system is used to manage the disk.
⇒ Interrupt is a signal.
Question 47 |
Which of the following disk scheduling strategies is likely to give the best through put?
Farthest cylinder next | |
Nearest cylinder next | |
First come first served | |
Elevator algorithm |
Nearest cylinder next - SSTF
First come first served - FCFS
Elevator - SCAN
SSTF always serves the request of nearest cylinder first. Due to which the necessary movement gets reduced.
Question 48 |
System calls are usually invoked by using
a software interrupt | |
polling | |
an indirect jump | |
a privileged instruction |
Question 49 |
A multi-user, multi-processing operating system cannot be implemented on hardware that does not support
Address translation | |
DMA for disk transfer | |
At least two modes of CPU execution (privileged and non-privileged) | |
Demand paging | |
Both A and C |
Question 50 |
Which of the following is/are advantage of virtual memory?
Faster access to memory on an average. | |
Processes can be given protected address spaces. | |
Linker can assign addresses independent of where the program will be loaded in physical memory. | |
Programs larger than the physical memory size can be run. | |
Both B and D |
B) True. Because in virtual memory concept of address translation provides protected address space so that one process do not interfere the other process.
C) False.
D) True.