Context-Free-Language
Question 1 |
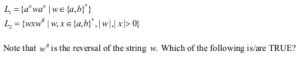
L 1 and L 2 are regular. | |
L 1 and L 2 are context-free. | |
L 1 is regular and L 2 is context-free. | |
L 1 and L 2 are context-free but not regular. |
Since no condition on the value of “n” is mentioned so for a particular case we can assume n=0, now when n=0 the language L1= w =(a+b)*
So if one case is (a+b)* then now even we assume any value of “n” the generated string will already present in (a+b)* thus L1=(a+b)*.
L2: In L2 the middle X can expand and consume all symbols of w except the first symbol and symbols of wr except the last symbol so L2 will be equivalent to language all strings start and end with the same symbol, hence L2 is regular.
Question 2 |
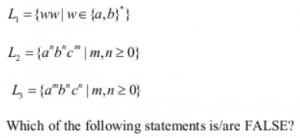
L 1 is not context-free but L 2 and L 3 are deterministic context-free. | |
Neither L 1 nor L 2 is context-free. | |
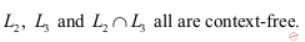 | |
Neither L 1 nor its complement is context-free. |
L2={an bn cm | m,n >=0} this contains only one comparison (number of a’s = number of b’s) so this is DCFL.
L3={am bn cn | m,n >=0} this contains only one comparison (number of b’s = number of c’s) so this is DCFL.
Intersection of L2 and L3 will have (number of a’s= number of b’s = number of c’s) i.e., {an bn cn | n >=0} so this is CSL (non-CFL).
So A is a true statement and rest all are false statements.
Question 3 |
Define for a context free language L ⊆ {0,1}*, init(L) = {u ∣ uv ∈ L for some v in {0,1}∗} (in other words, init(L) is the set of prefixes of L)
Let L = {w ∣ w is nonempty and has an equal number of 0’s and 1’s}
Then init(L) is
the set of all binary strings with unequal number of 0’s and 1’s | |
the set of all binary strings including the null string | |
the set of all binary strings with exactly one more 0’s than the number of 1’s or one more 1 than the number of 0’s | |
None of the above |
Question 4 |
The grammar whose productions are
  → if id then
  → if id then   else
  → id := id
is ambiguous because
the sentence if a then if b then c:=d | |
the left most and right most derivations of the sentence if a then if b then c:=d give rise top different parse trees | |
the sentence if a then if b then c:=d else c:=f has more than two parse trees | |
the sentence if a then if then c:=d else c:=f has two parse trees |
"if a then if b then c:=d else c:=f".
Parse tree 1:
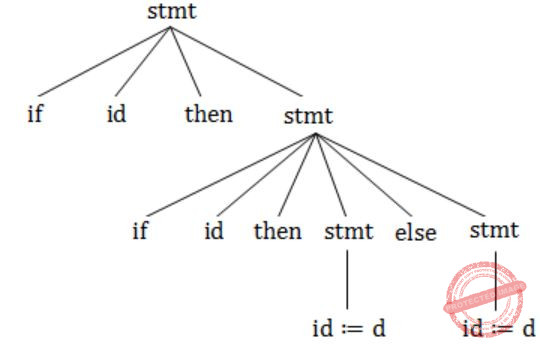
Parse tree 2:
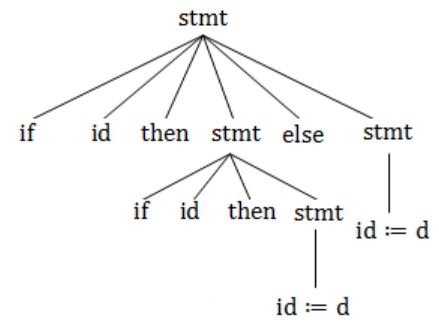
Question 5 |
G1: S → aSb|T, T → cT|ϵ
G2: S → bSa|T, T → cT|ϵ
The language L(G1) ∩ L(G2) is
Finite | |
Not finite but regular | |
Context-Free but not regular | |
Recursive but not context-free |
{ϵ, c, cc, ccc, … ab, aabb, aaabbb….acb, accb… aacbb, aaccbb, …}
Strings generated by G2:
{ϵ, c, cc, ccc, … ba, bbaa, bbbaaa….bca, bcca… bbcaa, bbccaa, …}
The strings common in L (G1) and L (G2) are:
{ϵ, c, cc, ccc…}
So, L (G1) ∩ L (G2) can be represented by regular expression: c*
Hence the language L (G1) ∩ L (G2) is “Not finite but regular”.
Question 6 |
Let L1 = {an bn cm│m,n ≥ 0} and L2 = {am bn cn│m,n ≥ 0}
Which of the following are context-free languages?
I. L1 ∪ L2
II. L1 ∩ L2
I only | |
II only | |
I and II | |
Neither I nor II |
Strings in L2 = {ϵ, a, aa, …., bc, bbcc,…., abc, aabc,…, abbcc, aabbcc, aaabbcc,..}
Strings in L1 ∪ L2 ={ϵ, a, aa, .., c, cc,.. ab, bc, …, aabb, bbcc,.., abc, abcc, aabc,…}
Hence (L1 ∪ L2) will have either (number of a’s = equal to number of b’s) OR (number of b’s = number of c’s).
Hence (L1 ∪ L2) is CFL.
Strings in L1 ∩ L2 = {ϵ, abc, aabbcc, aaabbbccc,…}
Hence (L1 ∩ L2) will have (number of a’s = number of b’s = number of c’s)
i.e., (L1 ∩ L2) = {anbncn | n ≥ 0} which is CSL.
Question 7 |
Context-free languages are closed under:
Union, intersection | |
Union, Kleene closure | |
Intersection, complement | |
Complement, Kleene closure |
By checking the options only option B is correct.
Question 8 |
Show that the language L = {xcx| x ∈ {0,1}* and c is a terminal symbol} is not context free, c is not 0 or 1.
Theory Explanation. |
Question 9 |
L={w x wR xR | w, x ∈ {0,1}* } | |
L={w wR x xR | w, x ∈ {0,1}* } | |
L={w x xR wR | w, x ∈ {0,1}* } | |
L={w x wR | w, x ∈ {0,1}* } |
Option A: L={w x wR xR | w, x ∈ {0,1}* }
This is not CFL as if we push “w” then “x” then we cannot match wR with “w” as top of stack contains x.
Option B: L={w wR x xR | w, x ∈ {0,1}* }
This is CFL. We non deterministically guess the middle of the string. So we push “w” then match with wR and again push x and match with xR
Option C: L={w x xR wR | w, x ∈ {0,1}* }
This is also CFL. We non deterministically guess the middle of the string. So we push “w” then push x and then match with xR and again match with wR
Option D: L={w x wR | w, x ∈ {0,1}* }
This is a regular language (hence CFL). In this language every string start and end with same symbol (as x can expand).
Question 10 |
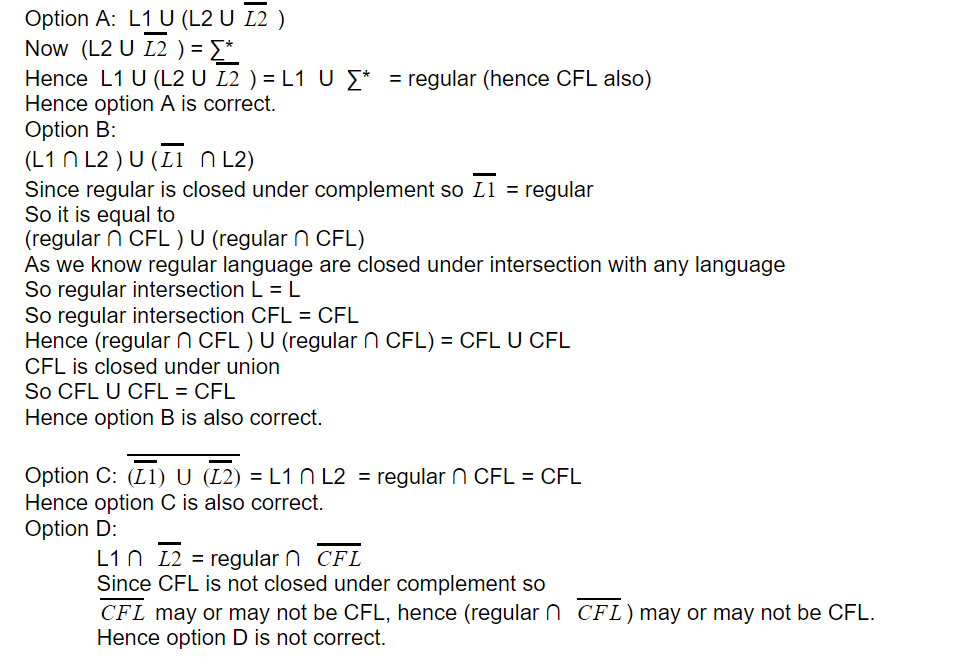
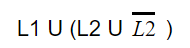 | |
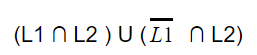 | |
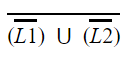 | |
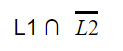 |
Question 11 |
The intersection of two CFL's is also a CFL.
True | |
False |
Question 12 |
L1 = {an bm cn+m: m,n ≥ 1}
L2= {an bn c2n: n ≥ 1}
Which one of the following is TRUE?
Both L1 and L2 are context-free. | |
L1 is context-free while L2 is not context-free. | |
L2 is context-free while L1 is not context-free. | |
Neither L1 nor L2 is context-free. |
At the end if input and stack is empty then accept.
Hence, it is CFL.
But L2 can’t be recognized by PDA, i.e. by using single stack.
The reason is, it has two comparison at a time,
1st comparison:
number of a’s = number of b’s
2nd comparison:
number of c’s must be two times number of a’s (or b’s)
It is CSL.
Question 13 |
Consider the languages:
L1 = {anbncm |n,m > 0} and L2 = {anbmcm |n,m > 0}
Which one of the following statements is FALSE?
L1 ∩ L2 is a context-free language | |
L1 ∪ L2 is a context-free language | |
L1 and L2 are context-free languages | |
L1 ∩ L2 is a context sensitive language |
CFL is not closed under Intersection.
L1 = {anbncm | n>0 & m>0}
L2 = {ambncn | n>0 & m>0}
L3 = L1 ∩ L2
={anbncn | n>0} It is not context-free.
Question 14 |
Consider the languages:
L1 = {wwR |w ∈ {0,1}*}
L2 = {w#wR | w ∈ {0,1}*}, where # is a special symbol
L3 = {ww | w ∈ (0, 1)*}
Which one of the following is TRUE?
L1 is a deterministic CFL
| |
L2 is a deterministic CFL | |
L3 is a CFL, but not a deterministic CFL | |
L3 is a deterministic CFL |
→ Given L1 is CFL but not DCFL.
→ Because, we can't predict where w ends and where it reverse is starts.
→ L2 = {w#wR | w ∈ (0,1)*}
→ Given L2 is CFL and also DCFL.
→ The string w and wR are separated by special symbol '#'.
→ L3 = {ww | w ∈ (0,1)*}
This is not even a CFL. This can be proved by using pumping lemma. So, L2 is DCFL. (✔️)
Question 15 |
Let L1 = {0n+m1n0m|n,m ≥ 0}, L2 = {0n+m1n+m0m|n,m ≥ 0}, and L3 = {0n+m1n+m0n+m|n,m ≥ 0}. Which of these languages are NOT context free?
L1 only | |
L3 only | |
L1 and L2 | |
L2 and L3 |
But for L2 and L3 PDA implementation is not possible. The reason is, in L2 there are two comparison at a time, first the number of 0’s in beginning should be equal to 1’s and then 0’s after 1’s must be less than or equal to number of 1’s. Suppose for initial 0’s and 1’s are matched by using stack then after matching stack will become empty and then we cannot determine the later 0’s are equal to or less than number of 1’s. Hence PDA implementation is not possible. Similarly L3 also has the similar reason.