Parsers
Question 1 |
The LALR (1) parser for a grammar G cannot have reduce-reduce conflict if the LR (1) parser for G does not have reduce-reduce conflict. | |
Symbol table is accessed only during the lexical analysis phase. | |
Data flow analysis is necessary for run-time memory management. | |
LR (1) parsing is sufficient for deterministic context-free languages. |
Symbol table is accessed in all the phases of compiler and not only in lexical analysis phase.
Data flow analysis is done in the control flow graph, in the code optimization phase. If LR(1) parses a grammar then definitely it is DCFL, so LR(1) parsing is sufficient for deterministic context-free languages.
Question 2 |
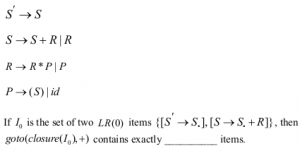
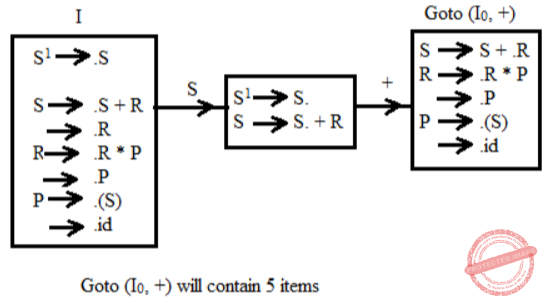
5 |
Question 3 |
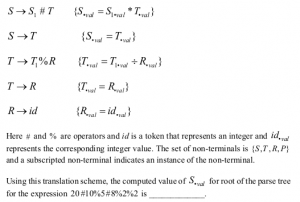
80 |
Question 4 |
Consider the following grammar.
     S → aSB|d
     B → b
The number of reduction steps taken by a bottom-up parser while accepting the string aaadbbb is _______.
7 |
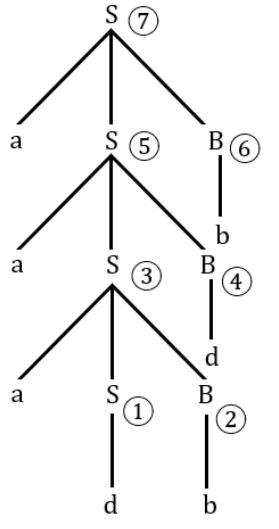
7 reductions total.
Question 5 |
stmt → if expr then expr else expr; stmt | ȯ
expr → term relop term | term
term → id | number
id → a | b | c
number → [0-9]
where relop is a relational operator (e.g., <, >, …), ȯ refers to the empty statement, and if, then, else are terminals.
Consider a program P following the above grammar containing ten if terminals. The number of control flow paths in P is ________. For example, the program
if e1 then e2 else e3 has 2 control flow paths, e1 → e2 and e1 → e3.
1024 | |
1025 | |
1026 | |
1027 |
if
if
:
:
:
(keep doing 10 times to get 10 'if')
We know that every if statement has 2 control flows as given in question. Hence,
We have 2 control flow choices for 1st 'if'
We have 2 control flow choices for 2nd 'if'
:
:
:
We have 2 control flow choices for 10th 'if'
Since all the choices are in one single structure or combination, so total choices are
2 × 2 × 2 × ........ 10 times = 210 = 1024
Question 6 |
Which of the following statements is true?
SLR parser is more powerful than LALR | |
LALR parser is more powerful than Canonical LR parser | |
Canonical LR parser is more powerful than LALR parser | |
The parsers SLR, Canonical CR, and LALR have the same power |
Canonical LR parser is more powerful than LALR parser.
Question 7 |
Which of the following is the most powerful parsing method?
LL (1) | |
Canonical LR | |
SLR | |
LALR |
LR > LALR > SLR
Question 8 |
Which of the following derivations does a top-down parser use while parsing an input string? The input is assumed to be scanned in left to right order.
Leftmost derivation | |
Leftmost derivation traced out in reverse | |
Rightmost derivation | |
Rightmost derivation traced out in reverse |
Bottom-Up parser - Reverse of rightmost derivation
Question 9 |
Which of the following statements is false?
An unambiguous grammar has same leftmost and rightmost derivation | |
An LL(1) parser is a top-down parser | |
LALR is more powerful than SLR | |
An ambiguous grammar can never be LR(k) for any k |
Option C: LALR is more powerful than SLR.
Option D: An ambiguous grammar can never be LR (k) for any k, because LR(k) algorithm aren’t designed to handle ambiguous grammars. It would get stuck into undecidability problem, if employed upon an ambiguous grammar, no matter how large the constant k is.
Question 10 |
Consider the following grammar with terminal alphabet ∑{a,(,),+,*} and start symbol E. The production rules of the grammar are:
              E → aA
              E → (E)
              A → +E
              A → *E
              A → ε
(a) Compute the FIRST and FOLLOW sets for E and A.
(b) Complete the LL(1) parse table for the grammar.
Theory Explanation is given below. |
Question 11 |
Assume that the SLR parser for a grammar G has n1 states and the LALR parser for G has n2 states. The relationship between n1 and n2 is:
n1 is necessarily less than n2 | |
n1 is necessarily equal to n2
| |
n1 is necessarily greater than n2
| |
None of the above |
Question 12 |
Consider the grammar shown below
S → i E t S S' | a
S' → e S | ε
E → b
In the predictive parse table. M, of this grammar, the entries M[S', e] and M[S', $] respectively are
{S'→e S} and {S'→ε} | |
{S'→e S} and { } | |
{S'→ε} and {S'→ε} | |
{S'→e S, S'→ε} and {S'→ε} |
First(S') = {e,ε}
First(E) = {b}
Follow(S') = {e,$}
Only when 'First' contains ε, we need to consider FOLLOW for getting the parse table entry.
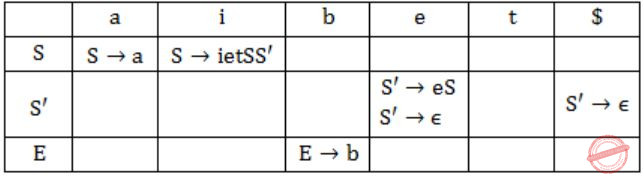
Hence, option (D) is correct.
Question 13 |
Consider the grammar shown below.
S → C C
C → c C | d
The grammar is
LL(1) | |
SLR(1) but not LL(1)
| |
LALR(1) but not SLR(1) | |
LR(1) but not LALR(1)
|
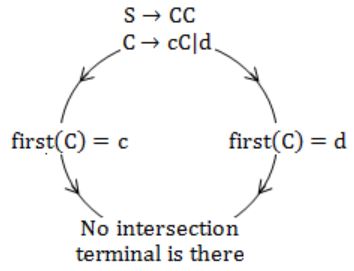
Hence, it is LL(1).
Question 14 |
Which of the following grammar rules violate the requirements of an operator grammar? P,Q,R are nonterminals, and r,s,t are terminals.
- (i) P → Q R
(ii) P → Q s R
(iii) P → ε
(iv) P → Q t R r
(i) only | |
(i) and (iii) only | |
(ii) and (iii) only | |
(iii) and (iv) only |
i) On RHS it contains two adjacent non-terminals.
ii) Have nullable values.
Question 15 |
The go to part of both tables may be different. | |
The shift entries are identical in both tables. | |
The reduce entries in the tables may be different. | |
The error entries in the tables may be different. |
Reduce entry and error entry may be different due to conflicts.
Question 16 |
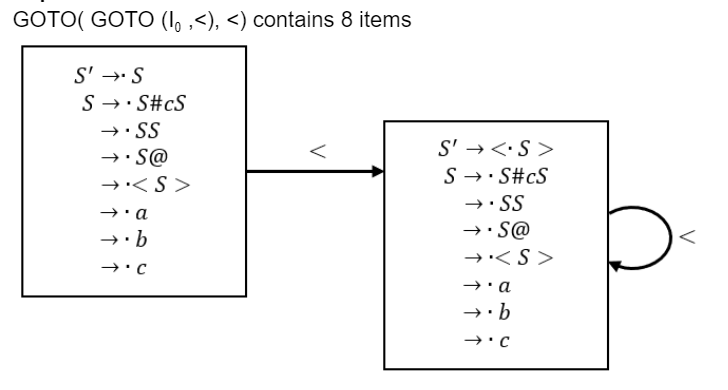
S’ ⟶ S
S ⟶ S#cS
S ⟶ SS
S ⟶ S@
S ⟶ < S >
S ⟶ a
S ⟶ b
S ⟶ c
Let I0=CLOSURE({S' ⟶.S}). The number of items in the set GOTO(GOTO(I0, <), <) is ____________.
8 |
Question 17 |
An operator precedence parser is a
Bottom-up parser. | |
Top-down parser. | |
Back tracking parser. | |
None of the above. |
Question 18 |
Merging states with a common core may produce __________ conflicts and does not produce ___________ conflicts in an LALR purser.
Reduce-Reduce, Shift-Reduce |
Question 19 |
Choose the correct alternatives (more than one may be correct) and write the corresponding letters only: Indicate all the true statements from the following:
Recursive descent parsing cannot be used for grammar with left recursion. | |
The intermediate form the representing expressions which is best suited for code optimization is the post fix form. | |
A programming language not supporting either recursion or pointer type does not need the support of dynamic memory allocation. | |
Although C does not support call by name parameter passing, the effect can be correctly simulated in C.
| |
No feature of Pascal violates strong typing in Pascal. | |
A and D |
(B) False.
(C) It is false. The language can have dynamic data types which required dynamically growing memory when data type size increases.
(D) Is true and using macro we can do this.
(E) Out of syllabus now.
Question 20 |
The grammar A → AA | (A) | ε is not suitable for predictive-parsing because the grammar is:
ambiguous | |
left-recursive | |
right-recursive | |
an operator-grammar |
It have A → AA has left recursion.
Question 21 |
Consider the grammar:
S → (S) | a
Let the number of states in SLR(1), LR(1) and LALR(1) parsers for the grammar be n1, n2 and n3 respectively. The following relationship holds good:
n1 < n2 < n3 | |
n1 = n3 < n2 | |
n1 = n2 = n3 | |
n1 ≥ n3 ≥ n2 |
→ LR(1) be the states of LR(1) items.
→ LR(0) items never be greater than LR(1) items then SLR(1) = LALR(1) < LR(1)
n1 = (n3) < (n2)
Question 22 |
Consider the following expression grammar. The semantic rules for expression calculation are stated next to each grammar production.
E → number 	 E.val = number. val
    |E '+' E 	 E(1).val = E(2).val + E>sup>(3).val
    |E '×' E	 E(1).val = E(2).val × E(3).val
The above grammar and the semantic rules are fed to a yacc tool (which is an LALR(1) parser generator) for parsing and evaluating arithmetic expressions. Which one of the following is true about the action of yacc for the given grammar?
It detects recursion and eliminates recursion
| |
It detects reduce-reduce conflict, and resolves
| |
It detects shift-reduce conflict, and resolves the conflict in favor of a shift over a reduce action | |
It detects shift-reduce conflict, and resolves the conflict in favor of a reduce over a shift action
|
Question 23 |
Consider the following expression grammar. The semantic rules for expression calculation are stated next to each grammar production.
E → number 	 E.val = number. val
    |E '+' E 	 E(1).val = E(2).val + E>sup>(3).val
    |E '×' E	 E(1).val = E(2).val × E(3).val
Assume the conflicts in Part (a) of this question are resolved and an LALR(1) parser is generated for parsing arithmetic expressions as per the given grammar. Consider an expression 3 × 2 + 1. What precedence and associativity properties does the generated parser realize?
Equal precedence and left associativity; expression is evaluated to 7
| |
Equal precedence and right associativity; expression is evaluated to 9 | |
Precedence of '×' is higher than that of '+', and both operators are left associative; expression is evaluated to 7 | |
Precedence of '+' is higher than that of '×', and both operators are left associative; expression is evaluated to 9 |
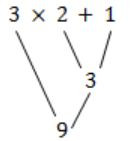
Hence, the answer is 9 and right associative.
Question 24 |
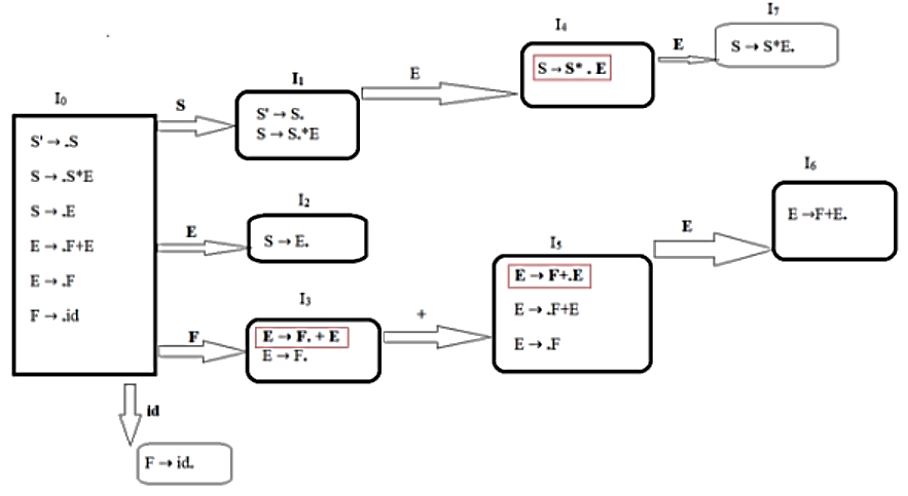
Consider the following grammar.
   S → S * E
   S → E
   E → F + E
   E → F
   F → id
Consider the following LR(0) items corresponding to the grammar above.
(i) S → S * .E
(ii) E → F. + E
(iii) E → F + .E
Given the items above, which two of them will appear in the same set in the canonical sets-of-items for the grammar?
(i) and (ii) | |
(ii) and (iii) | |
(i) and (iii) | |
None of the above |
Question 25 |
Consider the following grammar:
   S → FR
   R → S | ε
   F → id
In the predictive parser table, M, of the grammar the entries M[S,id] and M[R,$] respectively.
{S → FR} and {R → ε}
| |
{S → FR} and { } | |
{S → FR} and {R → *S} | |
{F → id} and {R → ε} |
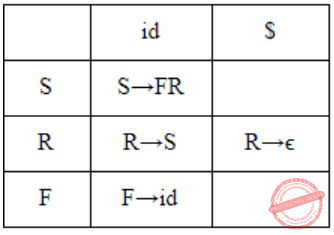
The representation M[X,Y] means X represents Variable (rows) and Y represents terminals (columns).
The productions are filled in parsing table by the below mentioned rules:
For every production P → α, we have:
Rule 1: If P → α is a production then add this production for each terminal “t” which is in FIRST of [α] i.e., ADD P → α to M[P, a]
Rule 2: If “ϵ” belongs to FIRST of [P] then add P → α to M[P, b] where “b” represents terminals FOLLOW[P].
By the above rules, we can see that production S → FR will go M[S, a] where “a” is FIRST [FR] which is equal to FIRST[F] = id, So S → FR will go in M[S,id].
Since in the production R→ϵ , FIRST[ϵ] = ϵ, hence the production will go in M[R, b] where “b” represents terminals FOLLOW[R] and FOLLOW[R] = $, so production R→ϵ will go in M[R,$]
Question 26 |
Which one of the following is a top-down parser?
Recursive descent parser. | |
Operator precedence parser. | |
An LR(k) parser.
| |
An LALR(k) parser. |
Question 27 |
Consider the grammar with non-terminals N = {S,C,S1},terminals T = {a,b,i,t,e}, with S as the start symbol, and the following set of rules:
      S --> iCtSS1|a
      S1 --> eS|ϵ
      C --> b
The grammar is NOT LL(1) because:
it is left recursive | |
it is right recursive | |
it is ambiguous | |
it is not context-free |
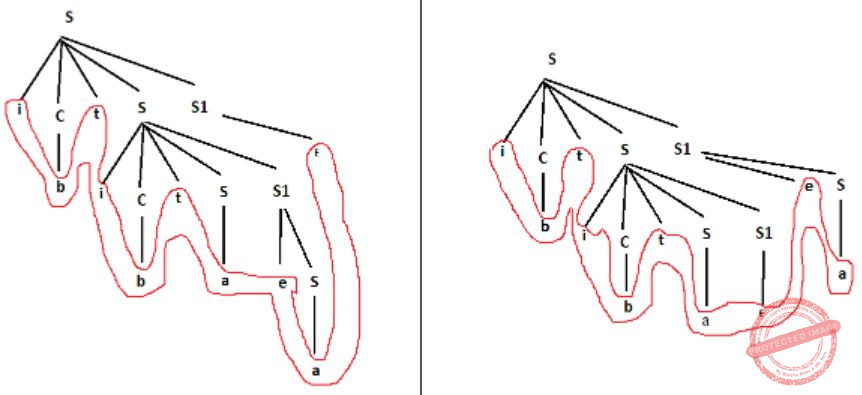
This grammar has two parse tree for string “ibt ibt aea”.
Question 28 |
Consider the following two statements:
P: Every regular grammar is LL(1)
Q: Every regular set has a LR(1) grammar
Which of the following is TRUE?
Both P and Q are true | |
P is true and Q is false | |
P is false and Q is true | |
Both P and Q are false |
For ex: Consider a regular grammar
S -> aS | a | ϵ
this grammar is ambiguous as for string "a" two parse tree is possible.
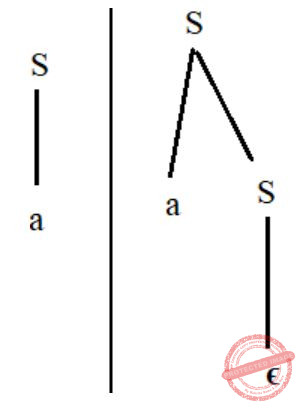
Hence it is regular but not LL(1).
But every regular set has a language accept or as DFA , so every regular set must have atleast one grammar which is unambiguous.
Hence, every regular set has LR(1) grammar.
Question 29 |
Among simple LR (SLR), canonical LR, and look-ahead LR (LALR), which of the following pairs identify the method that is very easy to implement and the method that is the most powerful, in that order?
SLR, LALR | |
Canonical LR, LALR | |
SLR, canonical LR | |
LALR, canonical LR |
Question 30 |
Consider the following grammar G.
  S → F ⎪ H
  F → p ⎪ c
  H → d ⎪ c
Where S, F and H are non-terminal symbols, p, d and c are terminal symbols. Which of the following statement(s) is/are correct?
- S1: LL(1) can parse all strings that are generated using grammar G.
S2: LR(1) can parse all strings that are generated using grammar
Only S1 | |
Only S2 | |
Both S1 and S2 | |
Neither S1 nor S2 |
For first production,

So, there is 'c' common in both the first(s) in the production of S. So not LL(1).
For LR(1),
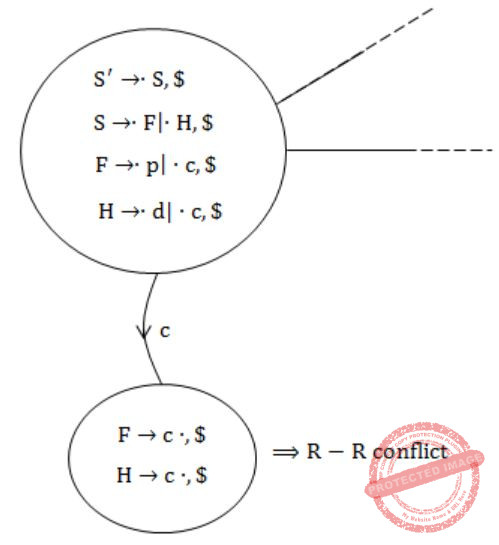
Since R-R conflict is present. So, not LR(1).
Hence, Option (D) is the correct answer.
Question 31 |
A shift reduce parser carries out the actions specified within braces immediately after reducing with the corresponding rule of grammar
S → xxW {print "1"}
S → y {print "2"}
W → Sz {print "3"}
What is the translation of xxxxyzz using the syntax directed translation scheme described by the above rules?
23131 | |
11233 | |
11231 | |
33211 |
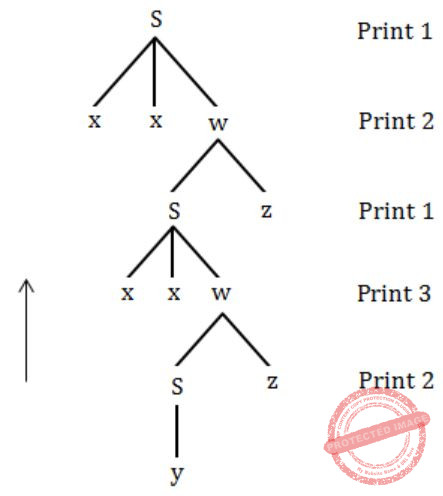
⇒ 23131
Note SR is bottom up parser.