Regular-Language
Question 1 |
If L is a regular language over Σ = {a,b}, which one of the following languages is NOT regular?
Suffix (L) = {y ∈ Σ* such that xy ∈ L} | |
{wwR │w ∈ L} | |
Prefix (L) = {x ∈ Σ*│∃y ∈ Σ* such that xy ∈ L} | |
L ∙ LR = {xy │ x ∈ L, yR ∈ L} |
Question 2 |
For Σ = {a,b}, let us consider the regular language L = {x|x = a2+3k or x = b10+12k, k ≥ 0}. Which one of the following can be a pumping length (the constant guaranteed by the pumping lemma) for L?
3 | |
9 | |
5 | |
24 |
For any language L, there exists an integer n, such that for all x ∈ L with |x| ≥ n, there exists u,v, w ∈ Σ*, such that x = uvw, and
(1) |uv| ≤ n
(2) |v| ≥ 1
(3) for all i ≥ 0: uviw ∈ L
We have to find "n" which satisfies for all the strings in L.
Considering strings derived by b10+12k.
The minimum string in L = "bbbbbbbbbb" but this string b10 cannot be broken in uvw.
So, pumping length 3, 9 and 5 cannot be the correct answer.
So, the minimum pumping length, such that any string in L can be divided into three parts "uvw" must be greater than 10.
Question 3 |
Which of the following languages is generated by the given grammar?
{anbm |n,m ≥ 0} | |
{w ∈ {a,b}* | w has equal number of a’s and b’s} | |
{an |n ≥ 0}∪{bn |n ≥ 0}∪{an b(sup>n|n ≥ 0} | |
{a,b}* |
Question 4 |
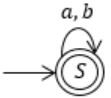
Language L2 is defined by the grammar: S2 → abS2|ε
Consider the following statements:
P: L1is regular
Q: L2is regular
Which one of the following is TRUE?
Both P and Q are true | |
P is true and Q is false | |
P is false and Q is true | |
Both P and Q are false
|
So, in order to compare equality between a’s and b’s memory (stack) is required.
Hence, L1 is not regular.
Moreover, L1 = {an bn | n ≥ 0} which is DCFL.
The language L2 generated by grammar contains repetition of “ab” i.e. L2 = (ab)* which is clearly a regular language.
Question 5 |
I. If all states of an NFA are accepting states then the language accepted by the NFA is Σ*.
II. There exists a regular language A such that for all languages B, A∩B is regular.
Which one of the following is CORRECT?
Only I is true | |
Only II is true | |
Both I and II are true | |
Both I and II are false |
The reason is NFA doesn’t have dead state, so even though all states are final state in NFA, the NFA will reject some strings.
For ex:
Consider L = a*b*
The NFA would be:

Even though all states are final states in above NFA, but it doesn’t accept string “aba”.
Hence its language can’t be ∑*.
Statement II is true:
Since A= Φ is a regular language and its intersection with any language B will be Φ (which is regular).
Question 6 |
Which of the following language is/are regular ?
- L1: {wxwR ⎪ w, x ∈ {a, b}* and ⎪w⎪, ⎪x⎪ >0} wR is the reverse of string w
L2: {anbm ⎪m ≠ n and m, n≥0}
L3: {apbqcr ⎪ p, q, r ≥ 0}
L1 and L3 only | |
L2 only | |
L2 and L3 only | |
L3 only |
L2: In this number of a's is dependent on number of b's. So PDA is needed.
L3: Any number of a's followed by any number of b's followed by any number of c's. Hence Regular.
Question 7 |
Which one of the following is TRUE?
The language L={an bn│n≥0} is regular. | |
The language L={an│n is prime} is regular. | |
The language L={w│w has 3k+1b's for some k∈N with Σ={a,b} } is regular. | |
The language L={ww│w∈Σ* with Σ={0,1} } is regular. |
L = {an | n is prime} is CSL, as calculation of “n is prime” can be done by LBA (Turing machine)
L = {ww | w ∈ ∑*} is CSL.
But L = { w | w has 3k+1 b’s for some k ∈ natural number} is regular.
Lets take values of k={1,2,3,….}
So number of b’s will be {4, 7, 10,……….} and number of a’s can be anything.
The DFA will be

Question 8 |
The length of the shortest string NOT in the language (over Σ = {a b,} of the following regular is expression is ______________.
a*b*(ba)*a*
3 | |
4 | |
5 | |
6 |
{ϵ, a, b, aa, ab, ba, bb}
Let’s check all the string of length 3.
The given regular expression generates {aaa, aab, aba, abb, baa, bba, bbb}
But it doesn’t generate the string “bab”, hence the shortest string not generated by regular expression has length 3 (string “bab”).
Question 9 |
If L1 = {an|n≥0} and L2 = {bn|n≥0}, consider
-
(I) L1·L2 is a regular language
(II) L1·L2 = {anbn|n≥0}
Which one of the following is CORRECT?
Only (I) | |
Only (II) | |
Both (I) and (II) | |
Neither (I) nor (II) |
Since L1 and L2 both are regular languages and regular languages are closed under concatenation. So their concatenation (i.e., L1⋅ L2) must also be a regular language.
So, L1⋅L2 = { anbn | n ≥ 0}
Hence, statement (i) is True but statement (ii) is False.
Question 10 |
Let L1 = {w ∈ {0,1}* |w has at least as many occurrences of (110)’s as (011)’s}. Let L2 = {w ∈ {0,1}*|w has at least as many occurrences of (000)’s as (111)’s}. Which one of the following is TRUE?
L1 is regular but not L2 | |
L2 is regular but not L1 | |
Both L1 and L2 are regular | |
Neither nor L1 are L2 regular |
{Number of occurrences of (110)} ≥ {Number of occurrences of (011)}
Lets analyse the language, consider a string in which occurrence of (110) is more than one.
The following possibilities are: {1100110, 1101110, 110110, ….}
Please observe whenever strings start with “11” then in every situation whatever comes after “11” the string will never violate the condition. So strings of the form 11(0+1)* will always satisfy the condition.
Consider a string in which occurrence of (011) is more than one.
The following possibilities are: {011011, 0111011, 0110011, ….}
In the following possibilities please observe that number of occurrence “011” is two but number of occurrence of (110) is one, which violate the conditions.
If we add “0” in every string mentioned above, i.e. {0110110, 01110110, 01100110, ….} Now, observe that number of occurrence “011” and the number of occurrence of (110) both are equal, which satisfies the conditions.
With these analysis, we can make the DFA , which is mentioned below.

But language L2 requires infinite comparison to count the occurrences of (000’s) and (111’s), hence it is not regular.
Question 11 |
Consider the languages L1 = ϕ and L2 = {a}. Which one of the following represents L1L2* ∪ L1*?
{є} | |
ϕ | |
a* | |
{є,a} |
Rϕ = ϕR = ϕ
So L1 L2 * = ϕ
and L1 * = {ϕ}* = {ϵ}
So L1L2* ∪ L1* = {ϵ}
Question 12 |
Consider the DFA given.

Which of the following are FALSE?
Which of the following are FALSE?
- 1. Complement of L(A) is context-free.
2. L(A) = L((11*0+0)(0 + 1)*0*1*)
3. For the language accepted by A, A is the minimal DFA.
4. A accepts all strings over {0, 1} of length at least 2.
1 and 3 only | |
2 and 4 only | |
2 and 3 only | |
3 and 4 only |
The regular expression corresponding to the given FA is

Hence we have regular expression: (11*0 +0) (0+1)*
Since we have (0+1)* at the end so if we write 0*1* after this it will not have any effect, the reason is whenever string ends with the terminals other than 1*0* there we can assume 1*0* as epsilon.
So it is equivalent to (11*0 +0) (0+1)*0*1*
The given DFA can be minimised, since the non-final states are equivalent and can be merged and the min DFA will have two states which is given below:

Hence statement 3 is false.
Since DFA accept string “0” whose length is one, so the statement “A accepts all strings over {0, 1} of length at least 2” is false statement.
Question 13 |
Given the language L ={ab,aa,baa}, which of the following strings are in L *?
-
1) abaabaaabaa
2) aaaabaaaa
3) baaaaabaaaab
4) baaaaabaa
1, 2 and 3 | |
2, 3 and 4 | |
1, 2 and 4 | |
1, 3 and 4 |
String 1: abaabaaabaa : ab aa baa ab aa
String 2: aaaabaaaa : aa aa baa aa
String 3: baaaaabaaaab: baa aa ab aa aa b, because of the last “b” the string cannot belong to L*.
String 4: baaaaabaa : baa aa ab aa
Question 14 |
Let P be a regular language and Q be a context-free language such that Q ⊆ P. (For example, let P be the language represented by the regular expression p*q* and Q be [pnqn | n ∈ N]). Then which of the following is ALWAYS regular?
P ∩ Q | |
P – Q | |
Σ* – P | |
Σ* – Q |
since regular languages are closed under complementation.
Question 15 |
Which of the following are regular sets?
- I. {anb2m | n≥0, m≥0}
II. {anbm | n=2m}
III. {anbm | n≠2m}
IV. {xcy | x,y∈{a,b}*}
I and IV only | |
I and III only | |
I only | |
IV only |
Statement II and III represent CFL, as it requires comparison between number of a’s and b’s.
Statement IV is also regular, and its regular expression is (a+b)* c (a+b)*.
Question 16 |
Which of the following languages is regular?
{wwR|w ∈ {0,1}+} | |
{wwRx|x, w ∈ {0,1}+} | |
{wxwR|x, w ∈ {0,1}+} | |
{xwwR|x, w ∈ {0,1}+} |
0 (0+1)+ 0 + 1 (0+1)+ 1
Any string which begins and ends with same symbol, can be written in form of “wxwr”
For example consider a string: 10010111, in this string “w=1” , “x= 001011” and wr = 1.
Hence any string which begins and ends with either “0” or with “1” can be written in form of “wxwr” and L = {wxwr | x,w ϵ {0,1}+} is a regular language.
Question 17 |
Which of the following is TRUE?
Every subset of a regular set is regular. | |
Every finite subset of a non-regular set is regular. | |
The union of two non-regular sets is not regular.
| |
Infinite union of finite sets is regular. |
Every subset of regular set is regular, is false. For example L = {an bn | n ≥ 0} is subset of ∑* and L is CFL, whereas ∑* is regular. Hence, every subset of regular set need not be regular.
The union of two non-regular sets is not regular, is also a false statement.
For example, consider two CFL’s.
L = {an bn | n ≥ 0} and its complement Lc = {am bn | m ≠ n } U b*a*.
If we take UNION of L and Lc , we will get ∑*, which is regular. Hence the UNION of two non-regular set may or may not be regular.
The statement, Infinite union of finite sets is regular is also a false statement.
Question 18 |
If s is a string over (0 + 1)* then let n0(s) denote the number of 0’s in s and n1(s) the number of 1’s in s. Which one of the following languages is not regular?
L = {s ∈ (0+1)* | n0(s) is a 3-digit prime} | |
L = {s ∈ (0+1)* | for every prefix s' of s,|n0(s') - n1(s')| ≤ 2} | |
L = {s ∈ (0+1)* |n0(s) - n1(s)| ≤ 4}
| |
L = {s ∈ (0+1)* | n0(s) mod 7 = n1(s) mod 5 = 0}
|
Option B: The DFA contains 6 states
State 1: n0(s') - n1(s') = 0
State 2: n0(s') - n1(s') = 1
State 3: n0(s') - n1(s') = 2
State 4: n0(s') - n1(s') = -1
State 5: n0(s') - n1(s') = -2
State 6: Dead state (trap state)
Hence it is regular.
Option D: Product automata concept is used to construct the DFA.
mod 7 has remainders {0,1,2,3,4,5,6} and mod 5 remainders {0,1,2,3,4}
So product automata will have 35 states.
But option C has infinite comparisons between number of 0’s and 1’s.
For ex: n0(s) = 5 and n1(s) = 1 then n0(s) - n1(s) = 4 and if n0(s) = 15 and n1(s) = 11 then n0(s) - n1(s) = 4.
Hence this is CFL.
Question 19 |
Consider the following two statements:
- S1: {02n|n≥1|} is a regular language
S2: {0m1n0m+n|m≥1 and n≥1|} is a regular language
Which of the following statements is correct?
Only S1 is correct | |
Only S2 is correct | |
Both S1 and S2 are correct | |
None of S1 and S2 is correct |
For S2, DFA is not possible which is not regular.
Question 20 |
Consider the following languages:
- L1 = {ww|w ∈ {a,b}*}
L2 = {wwR|w ∈ {a,b}*, wR is the reverse of w}
L3 = {02i|i is an integer}
L3 = {0i2|i is an integer}
Which of the languages are regular?
Only L1 and L2 | |
Only L2, L3 and L4 | |
Only L3 and L4 | |
Only L3 |
⇒ This is not regular language. We can't be able to identify where the 'w' will ends and where the next 'w' starts.
L2 = {wwR|w∈{a,b}*, wR is the reverse of w}
⇒ This also not a regular language. We can't identify where 'w' ends.
L4 = {0i2|i is an integer}
= {0i*0i|i is an integer}
⇒ This is also not a regular language. We can't identify where 0i ends.
L3 = {02i|i is an integer}
⇒ This is regular. We can easily find whether a string is even or not.