theory-of-computation
Question 1 |
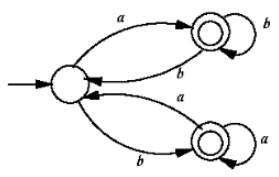
ab*bab* + ba*aba* | |
(ab*b)*ab* + (ba*a)*ba* | |
(ab*b + ba*a)* (a* + b*) | |
(ba*a + ab*b)* (ab* + ba*) |
(ab*b)*ab*+(ba*a)*ba* does not generate the string “abbaa” hence this is also wrong.
(ab*b+ba*a)*(a*+b*) generates epsilon hence this is also wrong.
(ab*b+ba*a)*(ab*+ba*) is the correct regular expression.
GATE 2022 Computer Science and Information Technology (CS)
Question 2 |
Every subset of a recursively enumerable language is recursive.
| |
If a language L and its complement L' are both recursively enumerable, then L must be recursive. | |
Complement of a context-free language must be recursive. | |
If L1 and L2 are regular, then L1 ∩ L2 must be deterministic context-free |
If L and L(complement) both are recursively enumerable then L must be recursive. It is a theorem.
Every CFL is CSL and CSL is closed under complement so complement of CFL must be CSL and every CSL is recursive. Thus the complement of CFL must be CSL, hence it must be recursive also.
If L1 and L2 are regular then their intersection must be regular, as regular languages are closed under intersection, so L1 intersection L2 must be regular, hence it must be DCFL, since every regular is also a DCFL.
Question 3 |
Given two Turing machines M1 and M2, decide if L(M1)=L(M2). | |
Given a Turing machine M, decide if L(M) is regular. | |
Given a Turing machine M, decide if M accepts all strings. | |
Given a Turing machine M, decide if M takes more than 1073 steps on every string. |
Checking whether a Turing machine accepts a regular language is also undecidable.
Completeness problem for recursively enumerable language is undecidable thus whether a Turing Machine accepts all strings is undecidable.
Whether a Turing machine takes more than 1073 steps is decidable as we need to run the Turing Machine only for 1073 steps so no chance of going into an infinite loop hence it is decidable.
Question 4 |
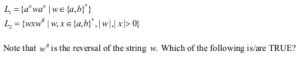
L 1 and L 2 are regular. | |
L 1 and L 2 are context-free. | |
L 1 is regular and L 2 is context-free. | |
L 1 and L 2 are context-free but not regular. |
Since no condition on the value of “n” is mentioned so for a particular case we can assume n=0, now when n=0 the language L1= w =(a+b)*
So if one case is (a+b)* then now even we assume any value of “n” the generated string will already present in (a+b)* thus L1=(a+b)*.
L2: In L2 the middle X can expand and consume all symbols of w except the first symbol and symbols of wr except the last symbol so L2 will be equivalent to language all strings start and end with the same symbol, hence L2 is regular.
Question 5 |
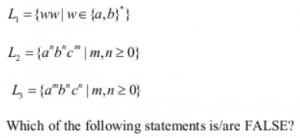
L 1 is not context-free but L 2 and L 3 are deterministic context-free. | |
Neither L 1 nor L 2 is context-free. | |
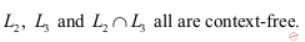 | |
Neither L 1 nor its complement is context-free. |
L2={an bn cm | m,n >=0} this contains only one comparison (number of a’s = number of b’s) so this is DCFL.
L3={am bn cn | m,n >=0} this contains only one comparison (number of b’s = number of c’s) so this is DCFL.
Intersection of L2 and L3 will have (number of a’s= number of b’s = number of c’s) i.e., {an bn cn | n >=0} so this is CSL (non-CFL).
So A is a true statement and rest all are false statements.
Question 6 |
Which of the following conversions is not possible (algorithmically)?
Regular grammar to context free grammar | |
Non-deterministic FSA to deterministic FSA | |
Non-deterministic PDA to deterministic PDA | |
Non-deterministic Turing machine to deterministic Turing machine |
Question 7 |
Which of the following features cannot be captured by context-free grammars?
Syntax of if-then-else statements | |
Syntax of recursive procedures | |
Whether a variable has been declared before its use | |
Variable names of arbitrary length |
Syntactic rules not checking the meaningful things such as if a variable is declared before it use (or) not.
Like this, things are handled by semantic analysis phase.
Question 8 |
The regular expression for the language recognized by the finite state automaton of figure is __________
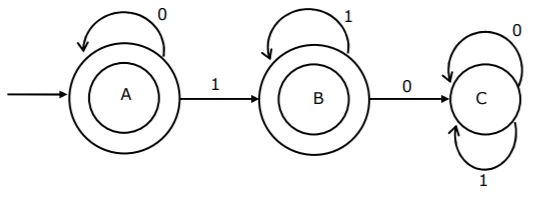
L = 0*1* |
L contains all binary strings where a 1 is not followed by a 0.
Question 9 |
Every subset of a countable set is countable.
State whether the above statement is true or false with reason.
True | |
False |
Question 10 |
(a) Given a set
S = {x| there is an x-block of 5's in the decimal expansion of π}
(Note: x-block is a maximal block of x successive 5’s)
Which of the following statements is true with respect to S? No reasons need to be given for the answer.
- (i) S is regular
(ii) S is recursively enumerable
(iii) S is not recursively enumerable
(iv) S is recursive
(b) Given that a language L1 is regular and that the language L1 ∪ L2 is regular, is the language L2 always regular? Prove your answer.
Theory Explanation. |
Question 11 |
A grammar G is in Chomsky-Normal Form (CNF) if all its productions are of the form A → BC or A → a, where A, B and C, are non-terminals and a is a terminal. Suppose G is a CFG in CNF and w is a string in L(G) of length, then how long is a derivation of w in G?
Theory Explanation. |
Question 12 |
Consider the language L = {an| n≥0} ∪ {anbn| n≥0} and the following statements.
- I. L is deterministic context-free.
II. L is context-free but not deterministic context-free.
III. L is not LL(k) for any k.
Which of the above statements is/are TRUE?
II only | |
III only | |
I only | |
I and III only |
We can make DPDA for this.

L is not LL(k) for any “k” look aheads. The reason is the language is a union of two languages which have common prefixes. For example strings {aa, aabb, aaa, aaabbb,….} present in language. Hence the LL(k) parser cannot parse it by using any lookahead “k” symbols.
Question 13 |
Consider the following statements.
- I. If L1 ∪ L2 is regular, then both L1 and L2 must be regular.
II. The class of regular languages is closed under infinite union.
Which of the above statements is/are TRUE?
Both I and II
| |
II only | |
Neither I nor II | |
I only
|
Assume L1 = {an bn | n>0} and L2 = complement of L1
L1 and L2 both are DCFL but not regular, but L1 U L2 = (a+b)* which is regular.
Hence even though L1 U L2 is regular, L1 and L2 need not be always regular.
Statement II is wrong.
Assume the following finite (hence regular) languages.
L1 = {ab}
L2 = {aabb}
L3 = {aaabbb}
.
.
.
L100 = {a100 b100}
.
.
.
If we take infinite union of all above languages i.e,
{L1 U L2 U ……….L100 U ……}
then we will get a new language L = {an bn | n>0}, which is not regular.
Hence regular languages are not closed under infinite UNION.
Question 14 |
Which one of the following regular expressions represents the set of all binary strings with an odd number of 1’s?
10*(0*10*10*)*
| |
((0 + 1)*1(0 + 1)*1)*10*
| |
(0*10*10*)*10* | |
(0*10*10*)*0*1
|
The regular expression ((0+1)*1(0+1)*1)*10* generate string “11110” which is not having odd number of 1’s , hence wrong option.
The regular expression (0*10*10*)10* is not a generating string “01”. Hence this is also wrong . It seems none of them is correct.
NOTE: Option 3 is most appropriate option as it generates the max number of strings with odd 1’s.
But option 3 is not generating odd strings. So, still it is not completely correct.
The regular expression (0*10*10*)*0*1 always generates all string ends with “1” and thus does not generate string “01110” hence wrong option.
Question 15 |
Which of the following languages are undecidable? Note that
- L1 =
L2 = {
L3 = {
L4 = {
L2 and L3 only
| |
L1 and L3 only
| |
L2, L3 and L4 only | |
L1, L3 and L4 only |
Only L3 is decidable. We can check whether a given TM reach state q in exactly 100 steps or not. Here we have to check only upto 100 steps, so here is not any case of going to infinite loop.
Question 16 |
Consider the following language.
L = {x ∈ {a,b}* | number of a’s in x is divisible by 2 but not divisible by 3}
The minimum number of states in a DFA that accepts L is ______.
6 |
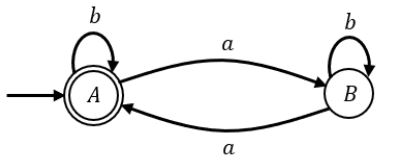
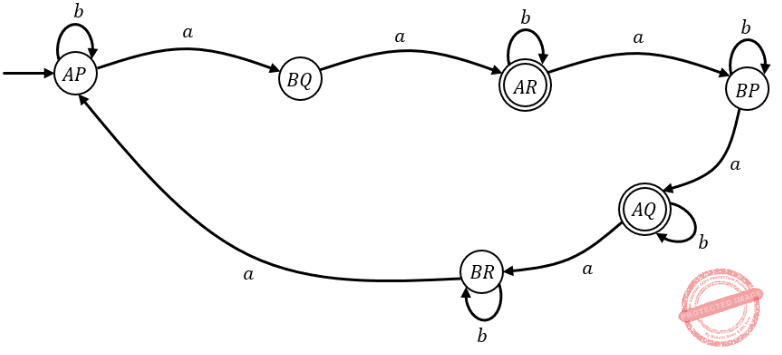
DFA 1: No. of a’s not divisible by 3
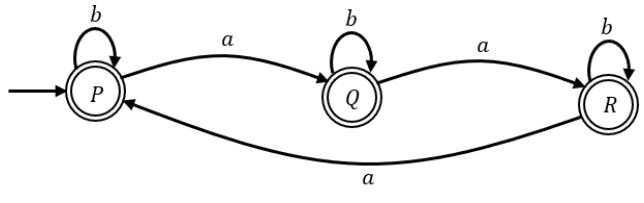
Using product automata:
Question 17 |
Consider the following languages.
- L1 = {wxyx | w,x,y ∈ (0 + 1)+}
L2 = {xy | x,y ∈ (a + b)*, |x| = |y|, x ≠ y}
Which one of the following is TRUE?
L1 is context-free but not regular and L2 is context-free. | |
Neither L1 nor L2 is context-free.
| |
L1 is regular and L2 is context-free.
| |
L1 is context-free but L2 is not context-free. |
So it is equivalent to
(a+b)+ a (a+b)+ a + (a+b)+ b (a+b)+ b
L2 is CFL since it is equivalent to complement of L=ww.
Complement of L=ww is CFL.
Question 18 |
Which two of the following four regular expressions are equivalent? (ε is the empty string).
- (i) (00)*(ε+0)
(ii) (00)*
(iii) 0*
(iv) 0(00)*
(i) and (ii) | |
(ii) and (iii) | |
(i) and (iii) | |
(iii) and (iv) |
In these two, we have any no. of 0's as well as null.
Question 19 |
Which of the following statements is false?
The Halting problem of Turing machines is undecidable. | |
Determining whether a context-free grammar is ambiguous is undecidbale. | |
Given two arbitrary context-free grammars G1 and G2 it is undecidable whether L(G1) = L(G2). | |
Given two regular grammars G1 and G2 it is undecidable whether L(G1) = L(G2). |
1) Membership
2) Emtiness
3) Finiteness
4) Equivalence
5) Ambiguity
6) Regularity
7) Everything
8) Disjointness
All are decidable for Regular languages.
→ First 3 for CFL.
→ Only 1st for CSL and REC.
→ None for RE.
Question 20 |
Let L ⊆ Σ* where Σ = {a, b}. Which of the following is true?
L = {x|x has an equal number of a's and b's } is regular | |
L = {anbn|n≥1} is regular | |
L = {x|x has more a's and b's} is regular | |
L = {ambn|m ≥ 1, n ≥ 1} is regular |
Here, m and n are independent.
So 'L' Is Regular.
Question 21 |
If L1 and L2 are context free languages and R a regular set, one of the languages below is not necessarily a context free language. Which one?
L1, L2 | |
L1 ∩ L2 | |
L1 ∩ R | |
L1 ∪ L2 |
Question 22 |
Define for a context free language L ⊆ {0,1}*, init(L) = {u ∣ uv ∈ L for some v in {0,1}∗} (in other words, init(L) is the set of prefixes of L)
Let L = {w ∣ w is nonempty and has an equal number of 0’s and 1’s}
Then init(L) is
the set of all binary strings with unequal number of 0’s and 1’s | |
the set of all binary strings including the null string | |
the set of all binary strings with exactly one more 0’s than the number of 1’s or one more 1 than the number of 0’s | |
None of the above |
Question 23 |
The grammar whose productions are
  → if id then
  → if id then   else
  → id := id
is ambiguous because
the sentence if a then if b then c:=d | |
the left most and right most derivations of the sentence if a then if b then c:=d give rise top different parse trees | |
the sentence if a then if b then c:=d else c:=f has more than two parse trees | |
the sentence if a then if then c:=d else c:=f has two parse trees |
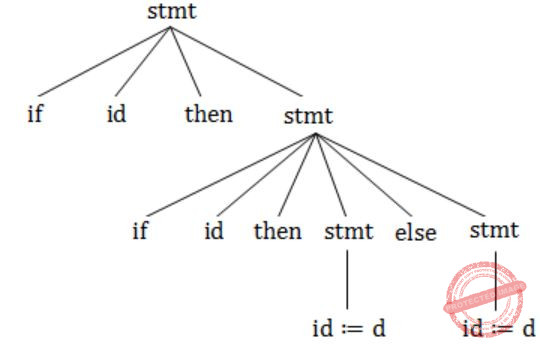
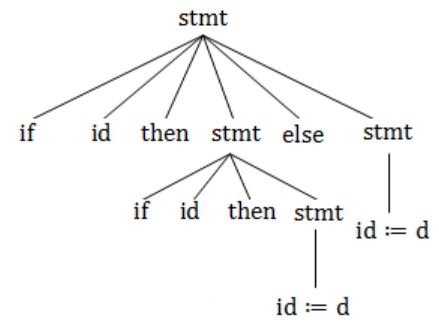
"if a then if b then c:=d else c:=f".
Parse tree 1:
Parse tree 2:
Question 24 |
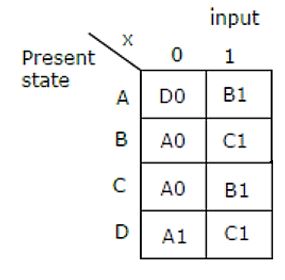
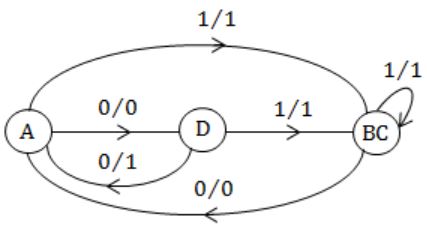
Consider the given figure of state table for a sequential machine. The number of states in the minimized machine will be
4 | |
3 | |
2 | |
1 |
Question 25 |
Let G be a context-free grammar where G = ({S, A, B, C},{a,b,d},P,S) with the productions in P given below.
   S → ABAC
   A → aA ∣ ε
   B → bB ∣ ε
   C → d
(ε denotes null string). Transform the grammar G to an equivalent context-free grammar G' that has no ε productions and no unit productions. (A unit production is of the form x → y, and x and y are non terminals.)
Theory Explanation. |
Question 26 |
Let Q = ({q1,q2}, {a,b}, {a,b,Z}, δ, Z, ϕ) be a pushdown automaton accepting by empty stack for the language which is the set of all non empty even palindromes over the set {a,b}. Below is an incomplete specification of the transitions δ. Complete the specification. The top of the stack is assumed to be at the right end of the string representing stack contents.
(1) δ(q1,a,Z) = {(q1,Za)}
(2) δ(q1,b,Z) = {(q1,Zb)}
(3) δ(q1,a,a) = {(.....,.....)}
(4) δ(q1,b,b) = {(.....,.....)}
(5) δ(q2,a,a) = {(q2,ϵ)}
(6) δ(q2,b,b) = {(q2,ϵ)}
(7) δ(q2,ϵ,Z) = {(q2,ϵ)} Theory Explanation. |
Question 27 |
Given Σ = {a,b}, which one of the following sets is not countable?
Set of all strings over Σ | |
Set of all languages over Σ | |
Set of all regular languages over Σ | |
Set of all languages over Σ accepted by Turing machines |
Question 28 |
Which one of the following regular expressions over {0,1} denotes the set of all strings not containing 100 as a substring?
0*(1+0)* | |
0*1010* | |
0*1*01 | |
0(10+1)* |
(B) generates 100 as substring.
(C) doesn't generate 1.
(D) answer.
Question 29 |
Which one of the following is not decidable?
Given a Turing machine M, a stings s and an integer k, M accepts s within k steps | |
Equivalence of two given Turing machines | |
Language accepted by a given finite state machine is not empty | |
Language generated by a context free grammar is non empty |
In (A) the number of steps is restricted to a finite number 'k' and simulating a TM for 'k' steps is trivially decidable because we just go to step k and output the answer.
(B) Equivalence of two TM's is undecidable.
For options (C) and (D) we do have well defined algorithms making them decidable.
Question 30 |
Which of the following languages over {a,b,c} is accepted by a deterministic pushdown automata?
Note: wR is the string obtained by reversing 'w'.
{w⊂wR|w ∈ {a,b}*} | |
{wwR|w ∈ {a,b,c}*} | |
{anbncn|n ≥ 0} | |
{w|w is a palindrome over {a,b,c}} |
(B) wwR, is realized by NPDA because we can't find deterministically the center of palindrome string.
(C) {anbncn | n ≥ 0} is CSL.
(D) {w | w is palindrome over {a,b,c}},
is realized by NPDA because we can't find deterministically the center of palindrome string.
Question 31 |
S → abScT | abcT
T → bT | b
Which one of the following represents the language generated by the above grammar?
{(ab)n (cb)n│n ≥ 1} | |
{(ab)n cb(m1 ) cb(m2 )…cb(mn )│n,m1,m2,…,mn ≥ 1} | |
{(ab)n (cbm)n│m,n ≥ 1} | |
{(ab)n (cbn)m│m,n ≥ 1} |
S→ abScT | abcT, this production will generate equal number of “ab” and “c” and for every “abc” any number of b’s ( > 1) after “abc”.
For Ex:
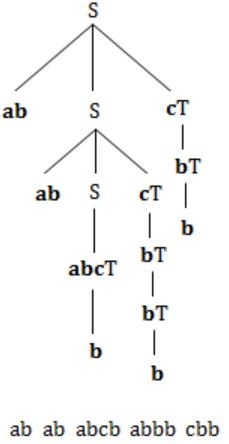
Hence the language generated by the grammar is
L = {(ab)n cb(m1 ) cb(m2 )…cb(mn )│n,m1,m2,…,mn ≥ 1}
Question 32 |
Consider the language L given by the regular expression (a+b)*b(a+b) over the alphabet {a,b}. The smallest number of states needed in deterministic finite-state automation (DFA) accepting L is _________.
4 | |
5 | |
6 | |
7 |

After converting the NFA into DFA:

After converting the NFA into DFA:

Question 33 |
S → SaS | aSb | bSa | SS | ϵ
where S is the start variable, then which one of the following strings is not generated by G?
abab | |
aaab | |
abbaa | |
babba |

But the string “babba” can’t be generated by the given grammar.
The reason behind this is, we can generate any number of a’s with production S→ SaS, but for one “b” we have to generate one “a”, as the production which is generating “b” is also generating “a” together (S→ aSb and S→ bSa).
So in string “babba” the first and last “ba” can be generated by S→ bSa, but we can’t generate a single “b” in middle.
In other words we can say that any string in which number of “b’s” is more than number of “a’s” can’t be generated by the given grammar.
Question 34 |
G1: S → aSb|T, T → cT|ϵ
G2: S → bSa|T, T → cT|ϵ
The language L(G1) ∩ L(G2) is
Finite | |
Not finite but regular | |
Context-Free but not regular | |
Recursive but not context-free |
{ϵ, c, cc, ccc, … ab, aabb, aaabbb….acb, accb… aacbb, aaccbb, …}
Strings generated by G2:
{ϵ, c, cc, ccc, … ba, bbaa, bbbaaa….bca, bcca… bbcaa, bbccaa, …}
The strings common in L (G1) and L (G2) are:
{ϵ, c, cc, ccc…}
So, L (G1) ∩ L (G2) can be represented by regular expression: c*
Hence the language L (G1) ∩ L (G2) is “Not finite but regular”.
Question 35 |
Let L1 = {an bn cm│m,n ≥ 0} and L2 = {am bn cn│m,n ≥ 0}
Which of the following are context-free languages?
I. L1 ∪ L2
II. L1 ∩ L2
I only | |
II only | |
I and II | |
Neither I nor II |
Strings in L2 = {ϵ, a, aa, …., bc, bbcc,…., abc, aabc,…, abbcc, aabbcc, aaabbcc,..}
Strings in L1 ∪ L2 ={ϵ, a, aa, .., c, cc,.. ab, bc, …, aabb, bbcc,.., abc, abcc, aabc,…}
Hence (L1 ∪ L2) will have either (number of a’s = equal to number of b’s) OR (number of b’s = number of c’s).
Hence (L1 ∪ L2) is CFL.
Strings in L1 ∩ L2 = {ϵ, abc, aabbcc, aaabbbccc,…}
Hence (L1 ∩ L2) will have (number of a’s = number of b’s = number of c’s)
i.e., (L1 ∩ L2) = {anbncn | n ≥ 0} which is CSL.
Question 36 |
Let A and B be finite alphabets and let # be a symbol outside both A and B. Let f be a total function from A* to B*. We say f is computable if there exists a Turing machine M which given an input x in A*, always halts with f(x) on its tape. Let Lf denote the language {x # f(x)│x ∈ A*}. Which of the following statements is true:
f is computable if and only if Lf is recursive. | |
f is computable if and only if Lf is recursively enumerable. | |
If f is computable then Lf is recursive, but not conversely. | |
If f is computable then Lf is recursively enumerable, but not conversely. |
Total function means for every element in domain, there must be a mapping in range.
Let us consider A= {a, b} and B = {0,1}
The concept of computing has been intuitively linked with the concept of functions.
A computing machine can only be designed for the functions which are computable.
The basic definition is:
Given a recursive language L and a string w over Σ*, the characteristic function is given by

The function “f” is computable for every value of "w".
However if the language L is not recursive, then the function f may or may not be computable.
Hence, f is computable iff Lf is recursive.
Question 37 |
If the regular set A is represented by A = (01 + 1)* and the regular set ‘B’ is represented by B = ((01)*1*)*, which of the following is true?
A ⊂ B | |
B ⊂ A | |
A and B are incomparable | |
A = B |
Question 38 |
Both A and B are equal, which generates strings over {0,1}, while 0 is followed by 1.
The numbers 1, 2, 4, 8, ……………., 2n, ………… written in binary | |
The numbers 1, 2, 4, ………………., 2n, …………..written in unary | |
The set of binary string in which the number of zeros is the same as the number of ones | |
The set {1, 101, 11011, 1110111, ………..} |
10, 100, 1000, 10000 .... = 10*
which is regular and recognized by deterministic finite automata.
Question 39 |
Regarding the power of recognition of languages, which of the following statements is false?
The non-deterministic finite-state automata are equivalent to deterministic finite-state automata. | |
Non-deterministic Push-down automata are equivalent to deterministic Push- down automata. | |
Non-deterministic Turing machines are equivalent to deterministic Push-down automata. | |
Both B and C |
C: Power (TM) > NPDA > DPDA.
Question 40 |
The string 1101 does not belong to the set represented by
110*(0 + 1) | |
1 ( 0 + 1)* 101 | |
(10)* (01)* (00 + 11)* | |
Both C and D |
C & D are not generate string 1101.
Question 41 |
How many sub strings of different lengths (non-zero) can be found formed from a character string of length n?
n | |
n2 | |
2n | |
 |
Possible sub-strings are = {A, P, B, AP, PB, BA, APB}
Go through the options.
Option D:
n(n+1)/2 = 3(3+1)/2 = 6
Question 42 |
Let L be the set of all binary strings whose last two symbols are the same. The number of states in the minimum state deterministic finite 0 state automaton accepting L is
2 | |
5 | |
8 | |
3 |
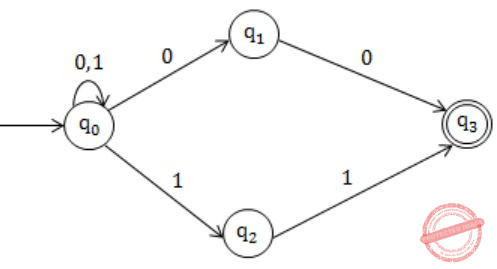
Equivalent DFA:
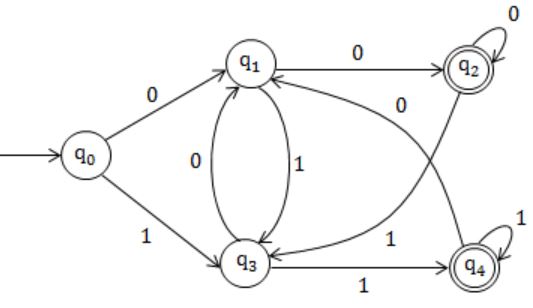
Hence, 5 states.
Question 43 |
Which of the following statements is false?
Every finite subset of a non-regular set is regular | |
Every subset of a regular set is regular | |
Every finite subset of a regular set is regular | |
The intersection of two regular sets is regular |
Question 44 |
Design a deterministic finite state automaton (using minimum number of states) that recognizes the following language:
L = {w ∈ {0,1}* | w interpreted as a binary number (ignoring the leading zeros) is divisible by 5}
Theory Explanation. |
Question 45 |
Let M = ({q0, q1}, {0, 1}, {z0, x}, δ, q0, z0, ∅) be a pushdown automaton where δ is given by
- δ(q0, 1, z0) = {(q0, xz0)}
δ(q0, ε, z0) = {(q0, ε)}
δ(q0, 1, X) = {(q0, XX)}
δ(q1, 1, X) = {(q1, ε)}
δ(q0, 0, X) = {(q1, X)}
δ(q0, 0, z0) = {(q0, z0)}
(a) What is the language accepted by this PDA by empty stack?
(b) Describe informally the working of the PDA.
Theory Explanation. |
Question 46 |
(a) Let G1 = (N, T, P, S1) be a CFG where,
N = {S1, A, B}, T = {a,b} and
P is given by
         S1 → aS1b             S1 → aBb
         S1 → aAb              B → Bb
         A → aA                B → b
         A → a
What is L(G1)?
(b) Use the grammar in part(a) to give a CFG
for L2 = {ai bj ak bl | i, j, k, l ≥ 1, i=j or k=l} by adding not more than 5 production rule.
(c) Is L2 inherently ambiguous?
Theory Explanation. |
Question 47 |
(a) An identifier in a programming language consists of upto six letters and digits of which the first character must be a letter. Derive a regular expression for the identifier.
(b) Build an LL(1) parsing table for the language defined by the LL(1) grammar with productions
Program → begin d semi X end
X → d semi X | sY
Y → semi s Y | ε
Theory Explanation. |
Question 48 |
Consider the regular expression (0 + 1) (0 + 1)…. N times. The minimum state finite automation that recognizes the language represented by this regular expression contains
n states | |
n + 1 states | |
n + 2 states | |
None of the above |
DFA:
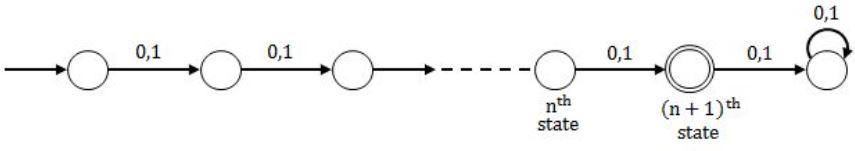
So, DFA requires (n+2) state.
NFA:
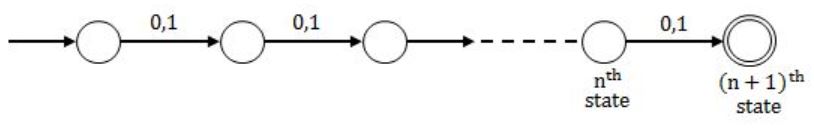
So, NFA requires (n+1) state.
So, final answer will be,
min(n+1, n+2)
= n+1
Question 49 |
Context-free languages are closed under:
Union, intersection | |
Union, Kleene closure | |
Intersection, complement | |
Complement, Kleene closure |
By checking the options only option B is correct.
Question 50 |
Let LD be the set of all languages accepted by a PDA by final state and LE the set of all languages accepted by empty stack. Which of the following is true?
LD = LE | |
LD ⊃ LE | |
LE = LD | |
None of the above |